Challenge
GfK data had to be downloaded manually from a website with a SAML-federated login.

Automated GfK data retrieval behind a SAML-protected login.
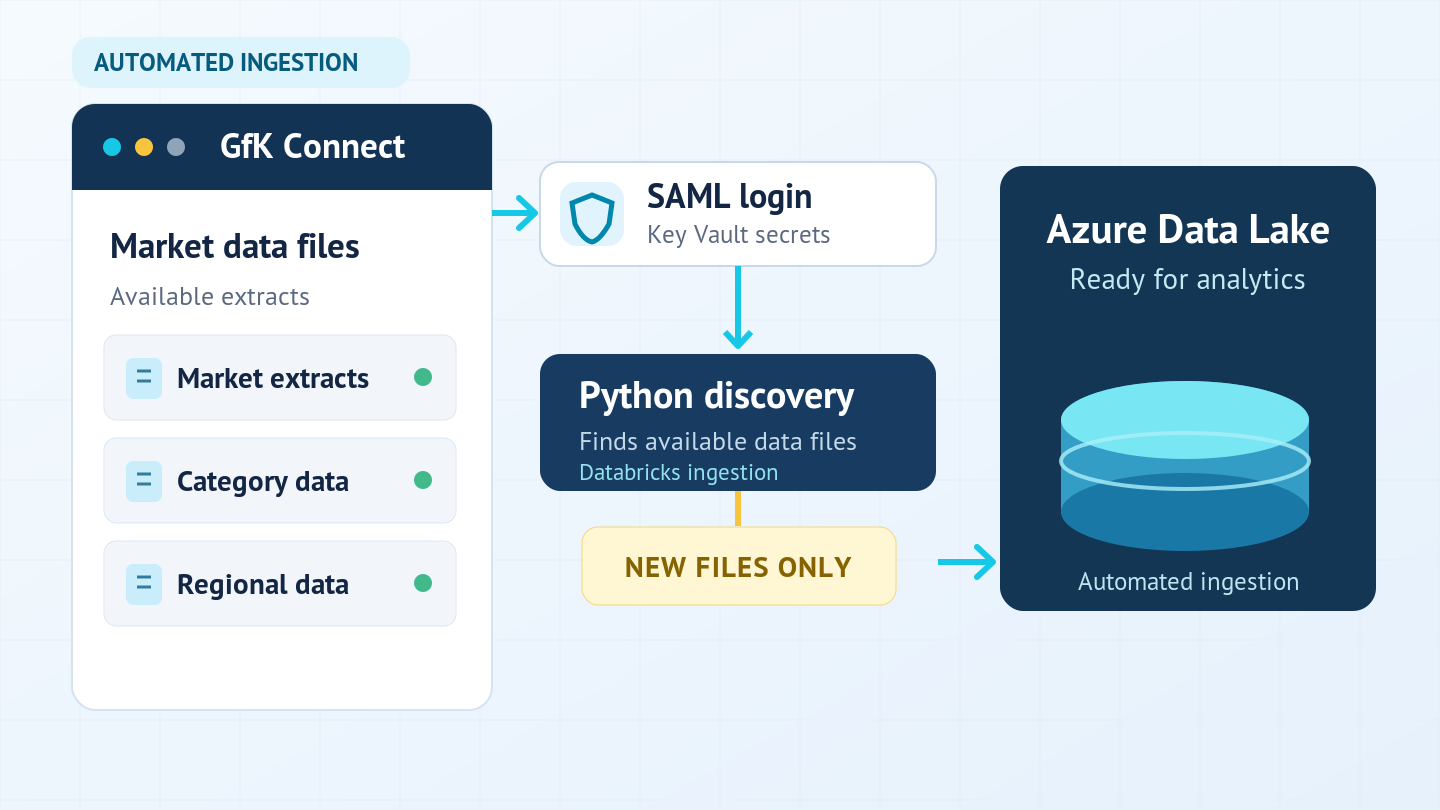
SAML login with credentials from Azure Key Vault, automatic file discovery and Databricks ingestion of new files into Azure Data Lake.
Challenge
GfK data had to be downloaded manually from a website with a SAML-federated login.
Delivered
A fully automated workflow for SAML login, file discovery and ingestion.
Enabled
New GfK files land in Azure Data Lake without manual steps or secrets in code.
GfK, a leading market research company, provides critical consumer goods data - but accessing it required manual downloads via a website, with login flow protected by SAML federation. Sourcing and integrating that data into a modern analytics layer was cumbersome and error-prone, and the manual step blocked any attempt at automation.
We built a fully automated workflow that handles SAML login, file discovery, and ingestion end-to-end. Authentication uses Python's Mechanize library to drive the GfK Federation login flow programmatically, with credentials retrieved at runtime from Azure Key Vault - secrets never live in code or config files.
Once authenticated, the system uses BeautifulSoup to scan the GfK Connect portal and extract the list of available data files automatically, eliminating the need for manual discovery. A Databricks Compute Cluster then orchestrates ingestion: it filters out files already processed and transfers only new data into the Azure Data Lake - efficient, scalable, and idempotent.
Python’s Mechanize drives the GfK Federation login flow, with credentials retrieved at runtime from Azure Key Vault.
BeautifulSoup scans the GfK Connect portal and extracts the list of available data files.
A Databricks Compute Cluster filters out files already processed and transfers only new data into Azure Data Lake.
Qualitative project outcomes; no measured savings are claimed.
Fully automated and secure data retrieval, eliminating the manual download step
Seamless integration with Azure cloud storage and downstream processing
Enhanced security: credentials managed via Azure Key Vault, never in source
Scalable architecture that adapts to growing data volumes and additional GfK feeds
Reproducible pattern reusable for any SAML-protected data source
Solution areas: Data Foundations

Choose a 30-minute conversation or send us a short enquiry - whichever works for you.